Clinical and epidemiological datasets routinely combine continuous, categorical, and binary variables with substantial fractions of missing values, a combination that most machine learning methods are not capable of handling. Our new preprint introduces POME, a self-supervised model that learns low-dimensional embeddings of both samples and variables from a bipartite graph representation of such data. On three real-world biomedical datasets, POME outperforms existing methods at imputation, identifies clinically meaningful patient subgroups without supervision, and supports zero-shot therapy recommendation. POME is available as open-source software on GitHub and PyPI.
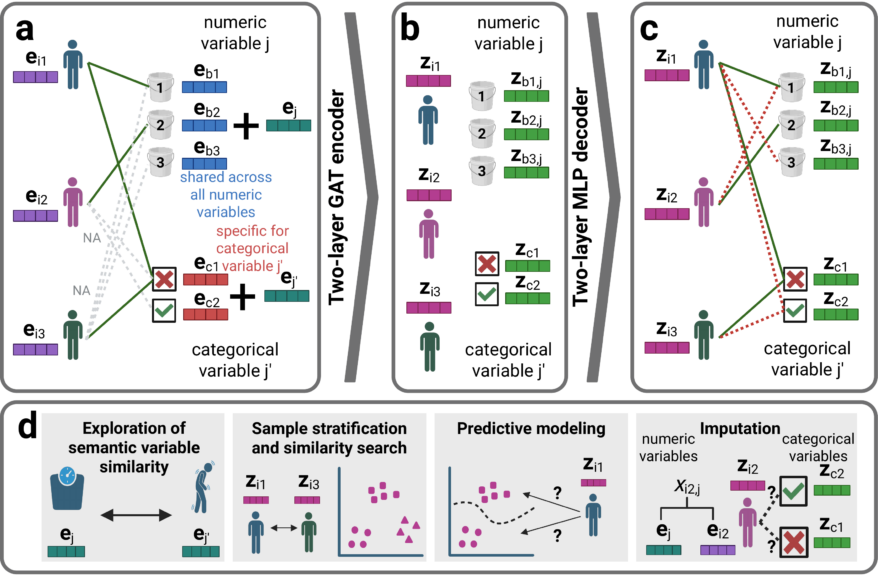
Clinical and epidemiological datasets routinely combine continuous, categorical, and binary variables with substantial fractions of missing values, a combination that most machine learning methods are not capable of handling. Our new preprint introduces POME, a self-supervised model that learns low-dimensional embeddings of both samples and variables from a bipartite graph representation of such data. On three real-world biomedical datasets, POME outperforms existing methods at imputation, identifies clinically meaningful patient subgroups without supervision, and supports zero-shot therapy recommendation. POME is available as open-source software on GitHub and PyPI.